Large language models (LLMs) are increasingly expected to produce responses that are accurate, helpful, safe, and aligned with human expectations. However, achieving reliable model behavior requires more than collecting large volumes of ordinary examples. The difficult, unusual, ambiguous, and unexpected inputs—commonly known as edge cases—can have an outsized impact on how well an AI system performs in real-world environments.
For teams developing RLHF & fine-tuning data, identifying and incorporating edge cases into training and evaluation datasets is therefore essential. These examples expose situations where a model's learned behavior may break down, helping teams improve alignment, robustness, and response quality.
What Are Edge Cases in RLHF?
An edge case is an input or interaction that falls outside the most common patterns represented in a dataset. It may involve ambiguous language, unusual phrasing, conflicting instructions, rare scenarios, cultural context, incomplete information, or attempts to manipulate the model.
For example, an LLM may perform well when asked a straightforward question such as, "Explain how photosynthesis works." Its behavior becomes more challenging when the prompt contains multiple interpretations, contradictory instructions, unusual terminology, or misleading assumptions.
In RLHF, these scenarios are valuable because human feedback helps define how a model should respond when the correct behavior is not obvious.
Why Edge Cases Matter for Model Alignment
RLHF relies on human preferences to guide model behavior. Annotators compare or evaluate candidate responses and identify which responses better satisfy predefined criteria such as helpfulness, accuracy, relevance, and safety.
If a dataset consists primarily of straightforward examples, the model may learn what to do under normal circumstances without developing sufficiently robust behavior for less predictable interactions.
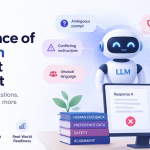
Edge cases help address this limitation by exposing models to situations where simple patterns are insufficient. They can reveal whether a model:
-
Recognizes ambiguity instead of making unsupported assumptions
-
Handles conflicting instructions appropriately
-
Distinguishes factual information from speculation
-
Responds consistently to unusual wording
-
Refuses inappropriate requests when necessary
-
Asks clarifying questions when information is insufficient
-
Maintains context across complicated conversations
This makes edge-case coverage an important component of alignment-focused dataset development.
Common Types of RLHF Edge Cases
Edge cases can take many forms, and their relevance varies according to the model's intended application.
1. Ambiguous Prompts
Some inputs can reasonably be interpreted in multiple ways. A high-quality model should recognize the ambiguity rather than confidently choosing an interpretation without sufficient evidence.
Annotators can label preferred responses that either ask for clarification or explicitly address multiple interpretations.
2. Conflicting Instructions
Users may provide instructions that contradict one another within the same prompt or conversation. These examples can help establish how models should prioritize and reconcile instructions.
3. Rare or Unusual Language
Typos, slang, incomplete sentences, dialect variations, mixed languages, and unconventional phrasing can challenge models trained predominantly on standardized text.
Including these examples can improve robustness across diverse user interactions.
4. Adversarial Inputs
Some prompts are intentionally designed to manipulate model behavior, bypass safeguards, or produce unreliable outputs. These cases are particularly valuable for safety-oriented RLHF datasets.
Annotators can evaluate whether candidate responses appropriately identify the underlying issue while remaining useful where possible.
5. Context-Dependent Scenarios
A response that is appropriate in one context may be unsuitable in another. Multi-turn conversations can introduce additional complexity when earlier information changes the meaning of a later request.
Context-rich edge cases can therefore help evaluate whether a model is actually using conversational context rather than responding to isolated keywords.
6. Knowledge Boundaries
Questions involving insufficient, uncertain, outdated, or contradictory information can expose whether a model acknowledges uncertainty appropriately.
These examples are particularly important for reducing overconfident responses and encouraging calibrated communication.
How Edge Cases Improve RLHF Dataset Quality
The value of edge cases extends beyond simply adding unusual prompts to a dataset. Their greatest benefit comes from systematically designing, annotating, reviewing, and evaluating them.
Better Behavioral Coverage
A dataset should represent the range of situations a model is likely to encounter. Edge cases expand this behavioral coverage by testing scenarios that conventional examples may overlook.
More Reliable Preference Signals
When annotators compare responses to difficult prompts, their judgments can provide valuable preference signals about nuanced behaviors. For example, one response may provide an immediate answer while another acknowledges uncertainty and requests additional information. Annotation criteria can determine which behavior is preferable in the relevant context.
Improved Robustness
Models trained primarily on predictable examples can struggle when inputs differ from familiar patterns. Carefully selected edge cases introduce greater variation and can encourage more robust response strategies.
Stronger Safety Testing
Safety-related edge cases can help teams identify failure modes before deployment. Instead of evaluating only obvious harmful requests, datasets can include indirect, ambiguous, or context-dependent attempts to elicit problematic outputs.
Building an Effective Edge-Case Annotation Process
Developing high-quality edge-case data requires a structured workflow.
Start with real-world failure modes. Model logs, user feedback, red-team exercises, and evaluation results can reveal recurring weaknesses. These observations can become candidates for new dataset examples.
Define annotation guidelines clearly. Annotators need explicit instructions explaining how to handle ambiguity, uncertainty, conflicting requirements, safety concerns, and other difficult scenarios.
Use multiple annotators where appropriate. Edge cases often involve subjective judgments. Independent annotations can reveal disagreement and identify examples that require expert review.
Track disagreement rather than hiding it. Annotator disagreement can itself be informative. High disagreement may indicate unclear guidelines, genuinely ambiguous prompts, or a need for additional domain expertise.
Review and iterate. Edge-case datasets should evolve as models, products, user behaviors, and known failure modes change.
The Role of Expert Annotation Services
Creating a strong RLHF dataset at scale can be challenging because edge cases often require more careful judgment than routine examples. Professional LLM & GenAI annotation services can support this process by combining trained annotators, quality-control workflows, domain-specific guidelines, and multi-stage review.
An experienced annotation partner can help organizations identify difficult examples, establish labeling taxonomies, conduct preference ranking, perform quality checks, and maintain consistency across large datasets.
For specialized applications, domain expertise may also be necessary. Healthcare, finance, legal, customer service, robotics, and other industries can involve terminology and risk considerations that general-purpose annotation workflows may not adequately capture.
Measuring Edge-Case Coverage
Adding edge cases is useful only when teams can measure whether coverage is improving. Organizations can track metrics such as:
-
Percentage of datasets representing identified failure modes
-
Annotator agreement on difficult examples
-
Model performance across edge-case categories
-
Safety evaluation results
-
Frequency of recurring failure patterns
-
Improvement after dataset updates
A dedicated edge-case evaluation set can also help teams compare model versions without relying exclusively on aggregate benchmark performance.
Conclusion
Edge cases are not simply unusual exceptions to normal model behavior. They provide valuable insight into how an LLM behaves when familiar patterns are insufficient. For RLHF dataset development, they can expose weaknesses in reasoning, instruction following, uncertainty handling, context management, and safety behavior.
A well-designed RLHF & fine-tuning data strategy should therefore combine broad coverage of common interactions with carefully selected difficult scenarios. By identifying real-world failure modes, applying consistent annotation guidelines, reviewing disagreement, and continuously expanding edge-case coverage, AI teams can build datasets that support more robust and dependable model behavior.
With structured LLM & GenAI annotation services, organizations can scale this process while maintaining the quality controls and domain expertise needed for complex RLHF workflows. The result is not merely a larger dataset, but a more informative one—capable of teaching models how to respond when real-world interactions become unpredictable.